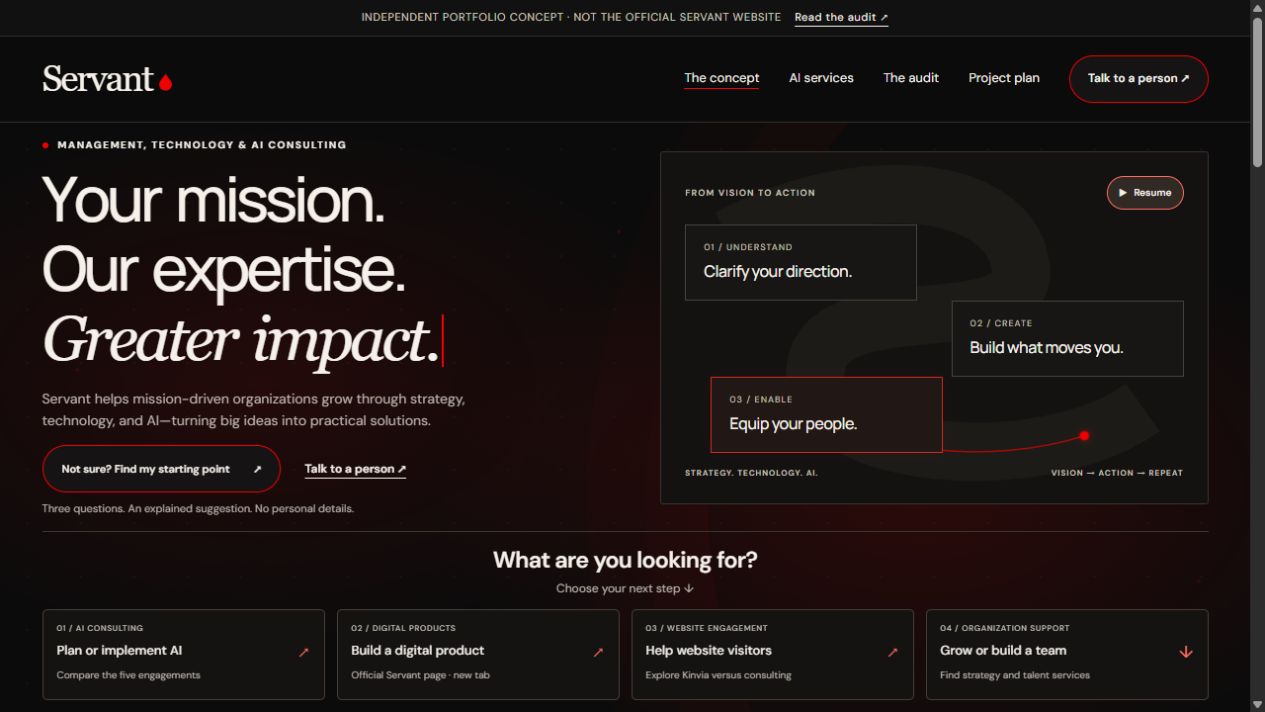
A fresh audit and working redesign concept exploring how mission-driven leaders could choose the right AI support—with clearer routes, comparable services, and an explained next step.
Self-initiated portfolio work, not commissioned by or affiliated with Servant. This is an AI-assisted coded proposal, not a production redesign. No participant research, business analytics, conversion lift, or accessibility conformance is claimed. The eight-week / 160-hour plan is future work allocation, not hours already worked.
The new audit replaces the September review with an October 15 baseline. The current Servant website already includes need-based AI links, a readiness assessment route, five consulting engagements, and Kinvia. Those existing strengths change the question from “what is missing?” to “what could make the choice easier to understand?”
How might we help a first-time visitor choose appropriate AI support and understand the next step, without asking them to become an AI expert first?
What the project now contains
A public-source review and selected desktop captures.
Five evidence-linked findings and improvement hypotheses.
A responsive coded homepage and AI service hub.
A rule-based guide, scripted helper, and next-step preview.
A detailed plan and documented technical checks.
My role and the use of AI
I’m developing this self-initiated project with AI assistance. AI supported the audit structure, interface copy, implementation, and test drafts; the concept and plan are collaborative outputs.
This page distinguishes existing evidence from proposals. Interviews, research synthesis, owner-approved content, and user validation are still planned. It does not present unperformed work as my completed contribution.
02 / THE CURRENT EXPERIENCE
Preserve the strengths. Be precise about the gaps.
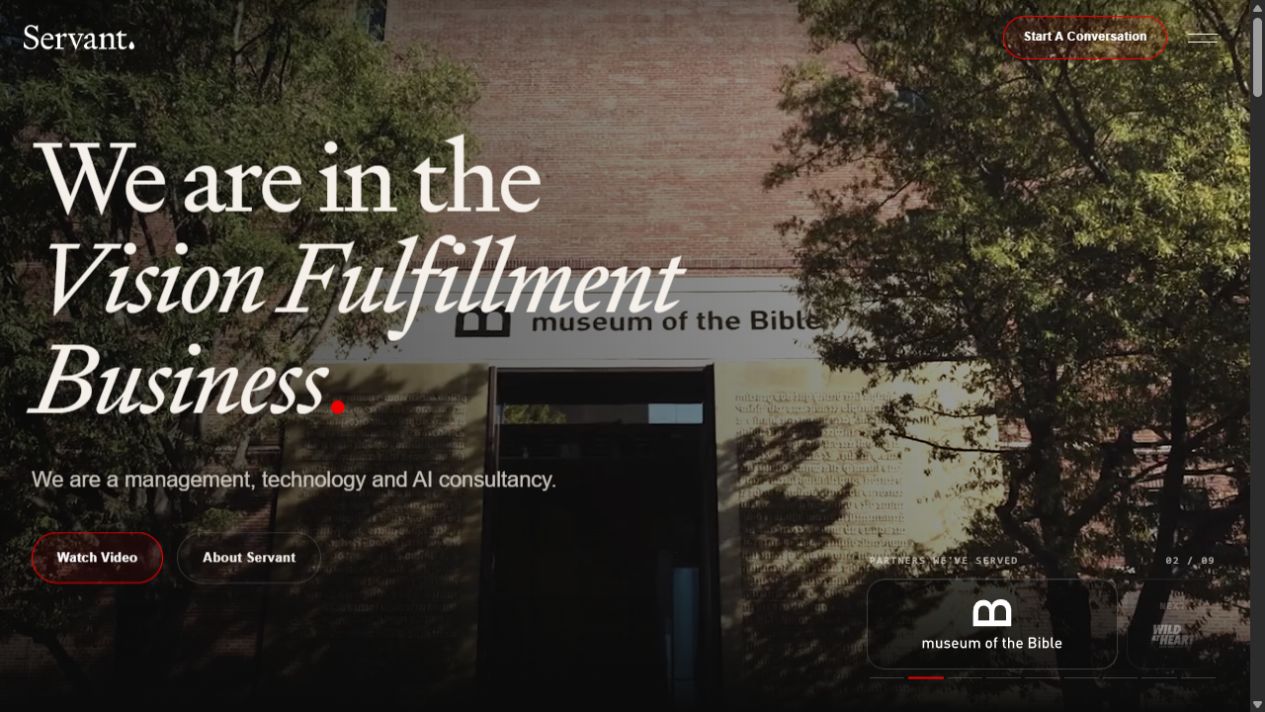
The baseline review covered the public homepage, AI Strategy page, and Ask Servant opening. The site’s mission-led identity, service table with timings, contact route, and assistant privacy link are foundations to retain.
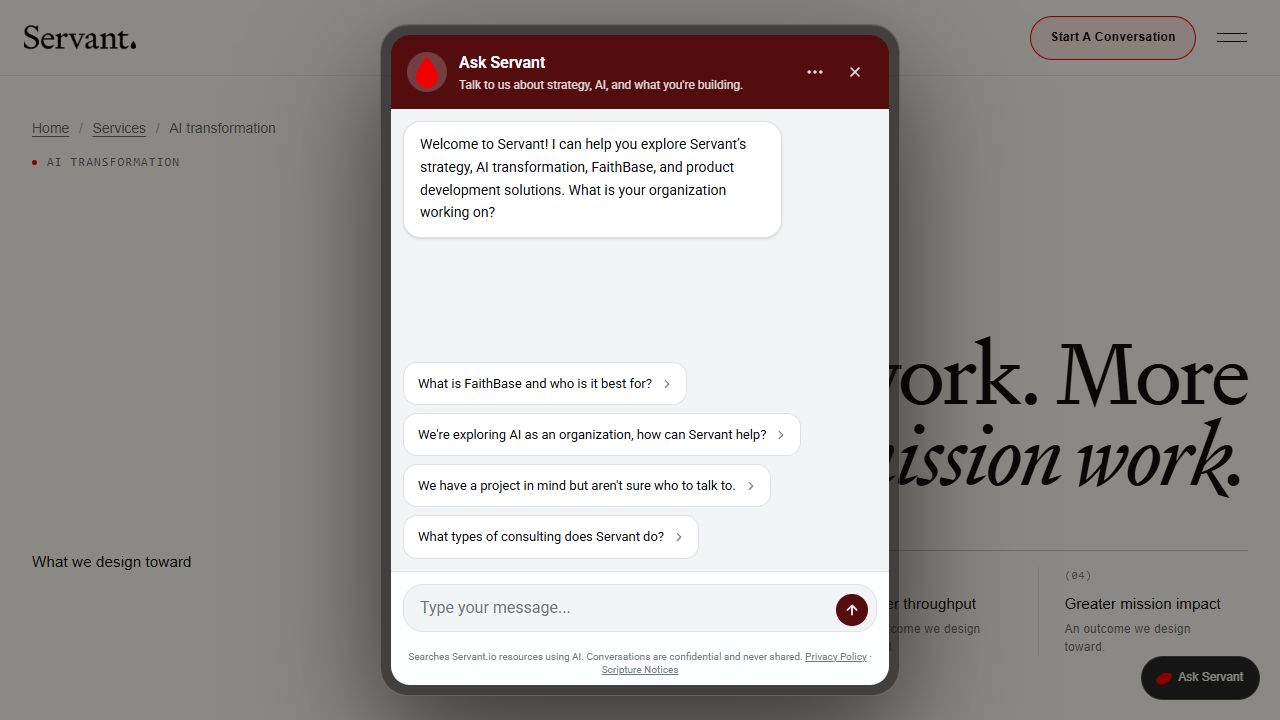
OBSERVED / Homepage opening. Need-based AI routes appear later on the page. Open original ↗OBSERVED / FaithBase wording in the assistant; the homepage links to Kinvia. No messages were submitted. Open original ↗
The naming difference is a directly observed content inconsistency. Earlier entry points, different comparison layouts, explained guidance, and clearer handoffs are hypotheses or proposed behavior—not proven user failures.
These are desktop observations. A matched live-site mobile baseline remains outstanding. Source and concept screenshots show implementation differences; they do not establish a usability improvement.
03 / WHAT CHANGES & WHY
Five focused changes. Each with a testable next step.
The fresh audit narrows the older findings into five clear opportunities. F2 is an observed inconsistency; F1, F3, F4, and F5 remain improvement hypotheses or proposed behavior. Priority should be revisited after research.
F1IMPROVEMENT HYPOTHESIS
Bring the choice forward.
Observation: The mission-led homepage already includes need-based AI routes further down. Their placement is observed; difficulty finding them has not been established.
Design response: Bring a plain-language entry action into the opening view, with direct service routes and broader company services still discoverable.
In the concept: The concept gives visitors an early route choice and a three-question starting-point guide.
Validate next: Ask participants to locate appropriate support without help; compare completion, first choice, and hesitation with the existing site.
F2OBSERVED INCONSISTENCY
Make product naming consistent.
Observation: The homepage links to Kinvia, while the opened Ask Servant greeting and suggested prompt still mention FaithBase. Their relationship is unconfirmed.
Design response: Confirm naming with an owner, then align labels, assistant prompts, destinations, and approved knowledge sources.
In the concept: The concept uses the currently linked Kinvia product route and explains product exploration separately from consulting. It does not assert an unverified rebrand.
Validate next: Check the content inventory and ask users to explain the difference between a website product and a consulting engagement.
F3IMPROVEMENT HYPOTHESIS
Make five engagements easier to compare.
Observation: The AI Strategy page already provides five engagements, outputs, and published timings. The review does not establish that the table is unusable.
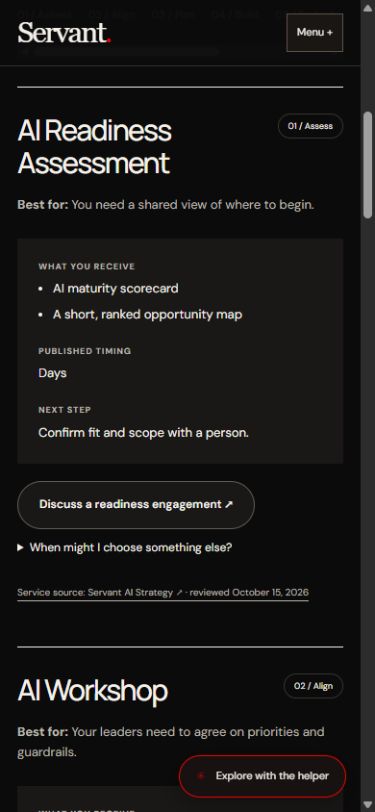
Design response: Use consistent “best for,” “what you receive,” “published timing,” and “next step” fields, stacking details on mobile.
In the concept: A shared content model renders all five services: readiness, workshop, blueprint, implementation sprints, and education/adoption. Published durations are context, not a project quote.
Validate next: Give two contrasting scenarios on desktop and mobile; ask participants to choose an engagement and explain their reasoning.
F4PROPOSED BEHAVIOR
Explain the recommendation.
Observation: The live assistant has starter prompts and a privacy disclosure. Answer accuracy and handoff behavior were not evaluated; no live messages were submitted.
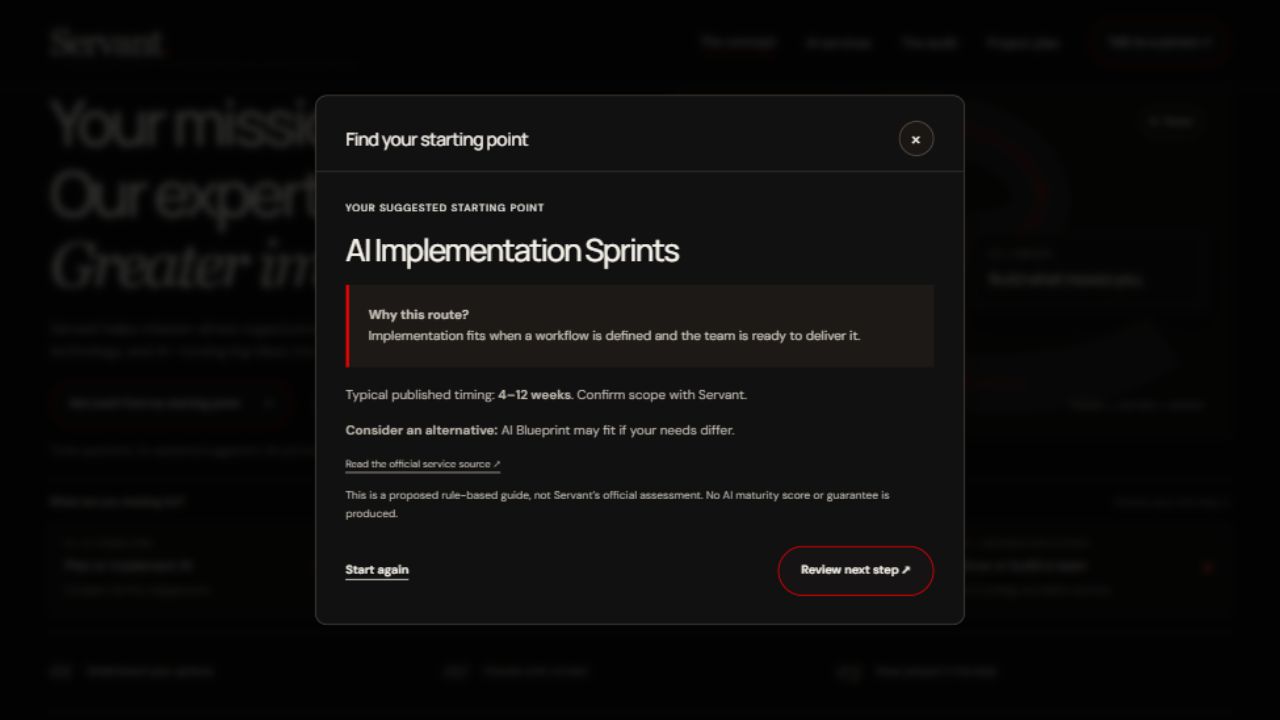
Design response: Show a route, a reason, an alternative, a source, and recovery options. Distinguish local rules from generative AI or an official maturity assessment.
In the concept: Three questions route to six possible destinations with explicit rules, back/restart, and a governance-uncertainty override. A scripted helper includes no-match handling and a person route.
Validate next: Exercise the rules and unsupported questions, then ask users to explain why a result appeared and whether any information was sent.
F5IMPROVEMENT HYPOTHESIS
Make the next step explicit.
Observation: Contact links and an external scheduling destination exist. Completion rates and causes of abandonment are unknown.
Design response: Explain the destination and what would happen to context before a visitor leaves. A real handoff would require permission before sharing information.
In the concept: A route-specific preview points to an official destination. It sends nothing, attaches no guide answers, collects no contact details, and creates no booking.
Validate next: Ask participants to find a person route, identify where it goes, and accurately explain whether their answers are shared.
04 / FROM AUDIT TO INTERACTION
A direction you can actually walk through.
The working concept moves beyond static recommendations. Its dark presentation uses bone text and red accents drawn from sampled public-site colors. The portfolio keeps its own orange identity around the case study.
IMPLEMENTED DEMO / Explained routing. This is fixed-rule guidance, not generative AI or an official readiness score. Open original ↗MOBILE CONCEPT / Stacked service details. Open the concept at your screen size to explore responsive behavior. Open original ↗
Bounded by design
The helper uses scripted local responses and a no-match fallback. There are no model API calls, live retrieval, CRM connections, actual bookings, or maturity scoring. The contact preview says nothing was sent and does not attach guide answers. External fonts, hosting, and official-site links have their own network behavior.
The lab’s October 15 QA record documents implementation checks. These results apply to the coded concept; they are not participant findings or a production quality certification.
Checks recorded as passed
14 expected-result routing scenarios and all 54 valid answer combinations; six allowed destinations and governance overrides covered.
Guide validation, a defined-build result, reason, alternative, timing, source, and disclaimer.
Contact preview disclosure; Escape closes it and focus returns to the trigger.
Scripted service response and an unsupported-question fallback.
Mobile menu, expandable service details, and all 42 plan tasks.
Document-level overflow checks at requested 390-pixel widths; later homepage checks at 320 pixels.
Motion Pause/Resume and the desktop hero/background bounds in the recorded viewport checks.
Still needs verification
Participant comprehension, confidence, and task success.
Complete keyboard/focus trapping and screen-reader behavior.
Comprehensive contrast, zoom, and accessibility testing.
Reduced-motion preference in a browser; CSS was reviewed statically.
A systematic, matched mobile baseline and full destination crawl.
Authorized analytics and production conversion measurement.
A sticky-header issue was found and fixed during prototype QA. The report retains the limits alongside passing checks.
Eight weeks of planned work. Evidence at every gate.
The plan allocates 20 focused hours per week across 42 ordered tasks. Its 160-hour total is a future work budget for one designer/developer, not tracked effort or a guaranteed delivery date. Recruitment, feedback, and approvals can extend elapsed time. The starter concept does not mean the planned research stages are complete.
Run five formative baseline sessions and five prototype sessions with comparable scenarios. Record unaided task completion, service-choice comprehension, time, assistance, and critical errors. At least 4 of 5 successful participants per core task is a proposed iteration threshold, not a measured result or population-level proof.
Conversion measurement would require an authorized production launch, agreed analytics, consent, baseline windows, and denominators. None is claimed here.
07 / LEARNING & PRACTICE
A stronger case study starts with a more careful audit.
The biggest lesson in the new review is to re-check an earlier assumption. The existing site already offers several features the first audit proposed. A credible recommendation should acknowledge what works, isolate the uncertainty, and specify how to test it.
Skills this project is developing
Evidence-led evaluation: dated captures and a clear distinction between observation and interpretation.
Information architecture: needs, service comparisons, product distinction, and meaningful next steps.
Interaction design: validation, back/restart, alternatives, unknown-answer handling, and honest feedback.
Prototype QA: routing scenarios, state behavior, mobile layout, and documented limitations.
What I’m carrying forward
Use AI to explore and build, then verify its output against source evidence. Make uncertainty visible. Avoid a confident result that the research cannot support.
The next contribution to document is my own research, alternatives, decisions, edits, and testing. Interviews and iteration should change this direction where evidence calls for it.
08 / SOURCES & DELIVERABLES
Open the evidence. Follow the work.
Public-source baseline reviewed October 15, 2026. Live pages can change. This portfolio is an independent study with no client endorsement; the original slide deck and official website remain unchanged.
The Google UX reference informs process only. This project is not Google-certified or endorsed. Product claims on vendor pages have not been independently validated here.